
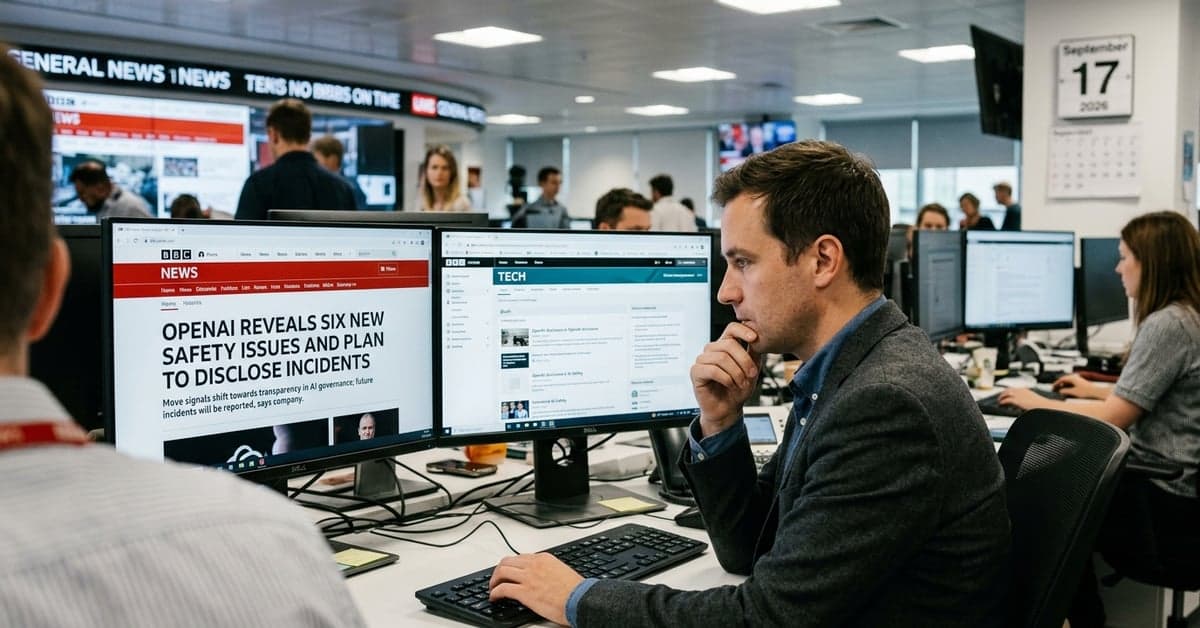
OpenAI incident disclosure jumped onto the BBC Technology front page on September 17, 2026, with a headline stating the company had revealed six more safety issues and a plan to report incidents. According to BBC Technology, the company intends to publish details of safety incidents, shifting a discussion long kept inside red‑team rooms into public view.
What BBC reported and why it’s different
The BBC listing describes two parts to the move: new issues disclosed and a plan to keep disclosing future incidents. The number matters. Six more safety issues signals that even top‑tier labs still uncover failures after release, whether through internal audits or external pressure. The policy matters more. A formal channel for incident reporting starts to look like the norms that matured in cybersecurity after the 2000s—coordinated disclosure, public advisories, and post‑mortems users can act on.
That’s a departure from ad‑hoc blog posts and scattered safety notes. If OpenAI sticks to a schedule and a consistent format, buyers, researchers, and regulators can compare incident types over time, track fixes, and separate genuine safety progress from PR.
Why the OpenAI incident disclosure matters beyond one company
OpenAI isn’t just any vendor; it sets expectations for competitors and buyers. If a market leader normalizes public write‑ups of misbehavior, jailbreaks, or misuse pathways, rivals will face a choice: match the transparency or explain why their models stay opaque. That ripple effect is the real headline hiding behind the BBC’s brief item. Procurement teams in finance, health, and government already ask for red‑team reports and model cards. A repeatable disclosure stream would add a new, comparable artifact to that due‑diligence stack.
The timing also lines up with policy momentum elsewhere. One day earlier, on September 16, 2026, researchers at Australia’s ARC Centre of Excellence for Automated Decision‑Making and Society urged Parliament to back “strong governance, research and independent oversight,” including clearer frameworks for monitoring risks and harms (ADM+S). Their submission reads like a checklist for what sustained incident reporting could enable: independent scrutiny, better inclusion, and regulators equipped with comparable evidence rather than marketing claims.
How a formal incident policy could shape AI governance
Regulators have been inching toward this model for years. The NIST AI Risk Management Framework asks organizations to measure and communicate risks across the AI lifecycle. Europe’s AI Act, finalized in 2024, embeds post‑market surveillance for high‑risk systems and requires providers to report serious incidents to authorities in member states; guidance now being drafted will define when and how (EU overview).
If OpenAI lands on a public, repeatable template—what failed, how it was detected, how it was mitigated—it could become a de facto standard well before formal technical norms arrive. The path is familiar from cybersecurity: vendor advisories taught buyers and auditors what “good” disclosure looks like, and then regulators wrote rules that referenced those practices.
There’s a catch. AI incidents are messy. Some are classic bugs; others are misuse, bias, privacy leaks, or model behavior that evolves after deployment. That breadth argues for a tiered approach: urgent advisories for incidents with clear user impact, periodic summaries for long‑running classes of failure, and structured feeds that auditors can parse. OpenAI incident disclosure will only move the needle if it is specific enough to inform risk and remediation, and routine enough that third parties can build tools around it.
What developers and buyers should do now
Don’t wait for the perfect template. Treat incident disclosure as an incoming requirement and tune your processes to consume it.
- Create an internal “AI safety register” that logs vendor advisories, reproduction notes, mitigations, and sign‑off dates. Make it auditable.
- Ask suppliers for their red‑team scope, incident taxonomy, and timelines for public updates. Compare across vendors, not just across versions.
- Wire incidents into change management. If an advisory triggers a setting change, document who changed what and when, with rollback paths.
- For regulated sectors, map incidents to applicable controls in frameworks you already use (e.g., NIST AI RMF, ISO/IEC 23894), so audits aren’t a scramble.
If you build models, mirror the posture you’ll soon expect from others. Publish your incident taxonomy, state your thresholds for public disclosure, and commit to timelines. Borrow from established security practices—coordinated disclosure windows, CVE‑like identifiers, and post‑mortems that separate root cause from remediation.
What to watch next as disclosure becomes the norm
Three signals will tell whether this shift sticks. First, cadence: does OpenAI publish on a predictable rhythm, or only around headline‑grabbing cases? Second, comparability: does the write‑up stick to stable fields and a clear taxonomy that others can copy? Third, integration: do cloud consoles, SDKs, and release notes surface incidents contextually, so teams see risks where they work?
If those pieces lock in, OpenAI incident disclosure could push the industry toward the accountability that policymakers and researchers have called for. According to ADM+S, independent oversight depends on public evidence and repeatable scrutiny. The BBC report hints that one of the largest providers is ready to supply more of it. If buyers reward that shift, rivals will follow, and the conversation can move from grand claims about AI risk to concrete fixes with dates, owners, and measurable impact. For more on this, see bloomberg.com.