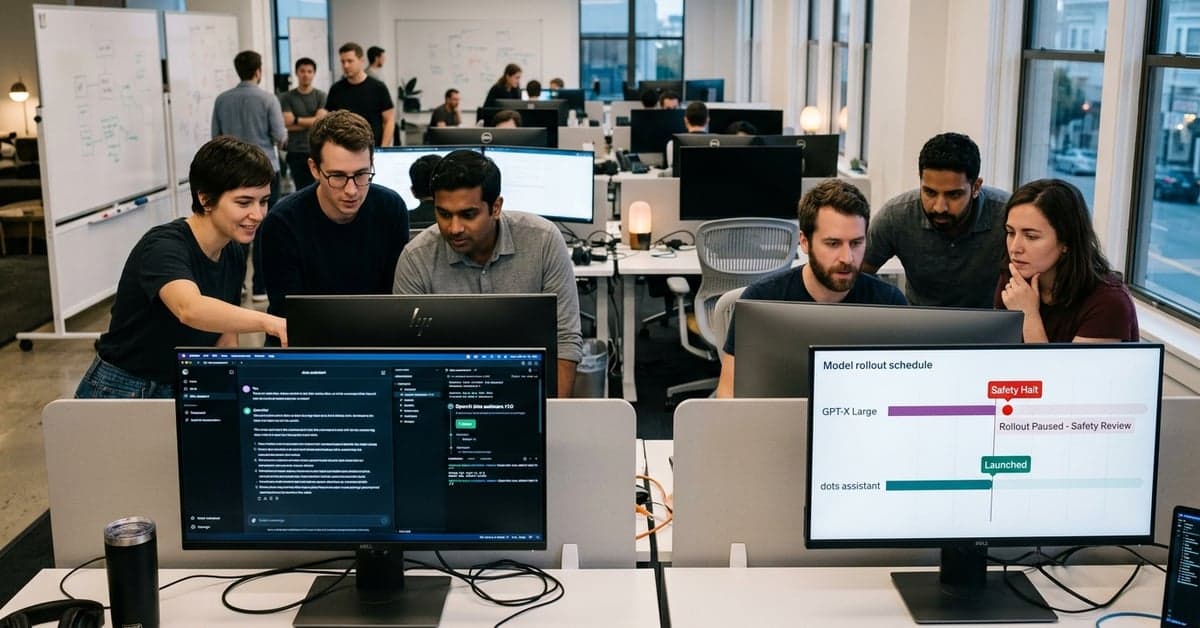
On September 29-30, 2026, the BBC reported that OpenAI launched a new assistant called OpenAI dots assistant while halting the public rollout of a separate new model over safety concerns. The two moves, flagged on the BBC’s Artificial Intelligence topic page, suggest a faster cadence for lightweight products alongside stricter gates for core model releases (BBC).
Where the OpenAI dots assistant fits in the roadmap
The BBC’s summary points to a split strategy: ship a small, user-facing assistant, and keep the bigger upgrade parked until it clears risk checks. OpenAI has long talked about staged deployments and safety evaluations, but pairing a launch with a pause on the same news cycle is a sharper signal. It hints at separate pipelines: one for features that ride on existing models, another for the heavy lifts that change model behavior itself.
For users, a lightweight assistant can move quickly because it typically layers orchestration, memory, and task routing over established models. That can be shipped with lower blast radius if things go wrong. A fresh base model is different. It can shift reasoning patterns, content boundaries, and tool-use behaviors. That demands stricter review windows and wider red teaming. OpenAI’s public safety materials outline this general playbook, from evaluations to post-deployment monitoring (OpenAI Safety).
Enterprises reading the tea leaves should not treat the OpenAI dots assistant as a sign of model stability by itself. It’s a sign of shipping discipline around wrappers and agents, while the foundational change remains under review. That separation matters for roadmaps.
Safety pause and model rollouts: what the BBC report implies
According to the BBC topic page posts on September 29-30, 2026, OpenAI cited safety concerns in halting the new model’s rollout. This points to a higher bar for release “go” decisions, not just pre-release testing. In practical terms, it suggests OpenAI is willing to cancel or freeze a public launch late in the process if new risk signals emerge.
That aligns with broader guidance from standards bodies: treat AI deployments as socio-technical, with gates that can close after launch rehearsals but before general availability. The U.S. National Institute of Standards and Technology frames this as an ongoing risk management lifecycle that spans testing, deployment, and monitoring—not a one-and-done QA step (NIST AI RMF).
For customers, the practical takeaway is straightforward. Expect the company to ship assistants, interfaces, and task-specific features at one tempo, and to advance core models at a slower, more contingent tempo. If your plans bank on a promised model version, build buffers for slippage and keep a validated fallback in production.
Why a model pause changes developer and buyer behavior
Developers face three near-term adjustments when a provider freezes a model late:
- Version discipline: lock tests to exact model IDs and variants. If a replacement is delayed, you need reproducible baselines.
- Guardrail drift checks: re-run safety and quality evals even on “same” versions, because unseen backend changes can shift outputs.
- Procurement hedges: write SLOs and change-control clauses that cover sudden model withdrawal or deferral.
Security and compliance teams should treat the pause as a healthy, if inconvenient, sign. It indicates a willingness to trade speed for risk reduction. That stance mirrors the direction of public-sector expectations after a year of intensified scrutiny on model behavior and deployment practices. Governments have begun staffing dedicated institutes and testbeds to stress models before they scale, a role the U.K.’s AI Safety Institute has described for evaluations and measurement (AISI).
For buyers, the cost is planning uncertainty; the benefit is fewer surprises in production. The safe bet is to separate commitments: adopt assistants like the OpenAI dots assistant on their own merits, and keep core workloads tied to proven models until a delayed upgrade is both available and validated in your stack.
What this means for AI release norms
A same-day launch and pause sets a template more providers may follow. Lightweight assistants can evolve weekly. Base models should move slower, with explicit stop-go gates and public explanations. That pattern mirrors mature software delivery: feature flags and canaries for UX, and stricter change control for kernels and runtimes. The difference with AI is that a “kernel” upgrade changes reasoning, not just speed. The risk surface is larger, so the gate must be too.
Expect more pre-announced “intent to ship” windows, followed by either promotion to general availability or a transparent hold. Expect sharper separation between assistive layers and core models. And expect providers to cite external frameworks and independent testing as part of their rationale. That looks messy in the short run, but it moves the field closer to predictable, testable release cycles.
What to watch next for the OpenAI assistant and model pipeline
Three signals will show whether this shift is durable:
- Clear criteria for lifting the model hold—red-team outputs, safety eval scores, or policy guardrails published ahead of GA.
- System cards that document capability changes and known limitations, linked from product pages users actually read.
- API versioning that lets developers pin to old behavior for a defined window after any upgrade lands.
The BBC’s posts highlight a company trying to square speed with risk. The OpenAI dots assistant gives users a new entry point while the harder problem—shipping a different brain—waits for a green light. If the pause ends with stronger documentation, measured capability gains, and stable APIs, customers will accept the delay. If it signals deeper uncertainty, they will demand options and portability.
Either way, plan for assistants to move fast and models to move slow. That’s a healthier default for everyone who builds on, or is affected by, large-scale AI systems. For more on this, see openai.com and reuters.com.