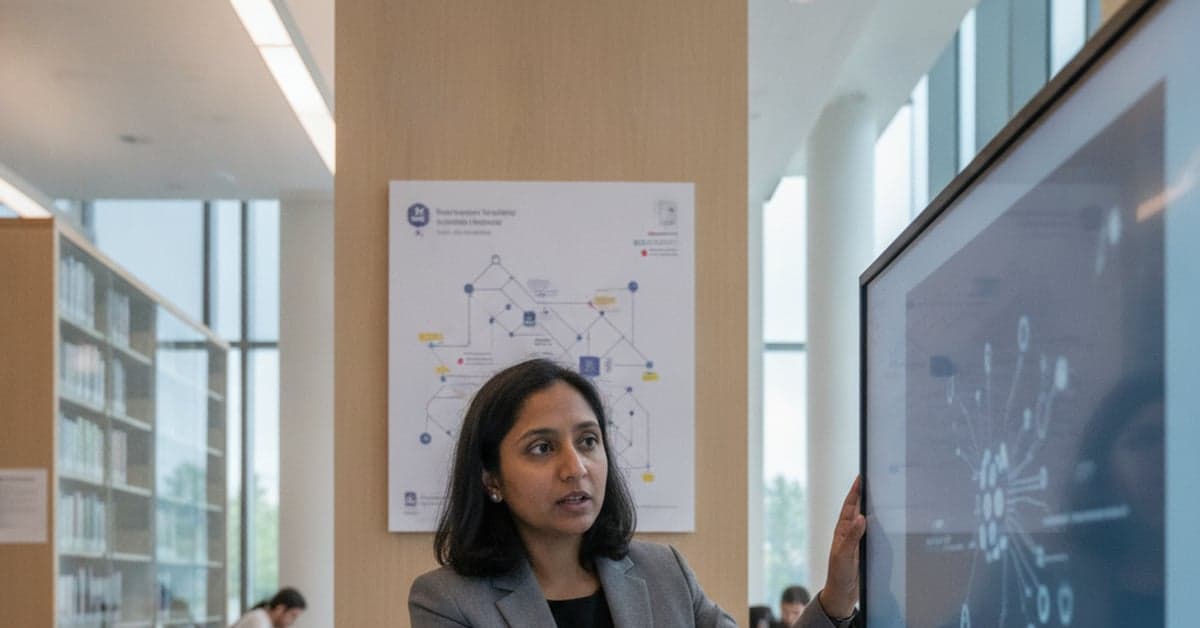
On September 28, 2026, a poster published through the International Federation of Library Associations and Institutions detailed how a dashboard built on EZproxy logs, machine learning, and a conversational assistant can reshape collection decisions. The project, by Vanessa Ramesh Mahboobani, centers on an analytics layer that flags duplicate access to the same title across platforms, forecasts usage, and adds a chatbot interface to query complex data in plain language. It’s a concrete blueprint for where library generative AI can move from novelty to day-to-day decisions (IFLA repository).
Inside the library generative AI pilot: architecture and data
The work starts with EZproxy, which records authenticated access to licensed e-resources. Those logs, when normalized and joined across vendors, reveal who accessed what, when, and from where in the campus context. OCLC describes EZproxy as a secure way to route users through a proxy while keeping access simple, which also makes its logs a rich, if messy, source for usage patterns (OCLC).
According to the IFLA poster, the dashboard mines those logs to:
- Identify the same publication accessed via multiple databases, signaling costly duplication.
- Surface hidden trends across user segments, highlighting programs or departments driving demand.
- Feed a prediction model that forecasts e-resource usage based on observed patterns.
- Expose results through a generative AI chatbot that returns summaries and subscription recommendations.
That stack ties three library needs together: visibility, foresight, and speed. Visibility comes from unified EZproxy analytics. Foresight comes from usage prediction. Speed comes from a conversational layer that can answer, “Where are we overpaying for redundancy?” or, “Which titles are spiking ahead of semester start?” without a week of ad‑hoc SQL.
Where generative AI in libraries changes decisions
Duplicate access is an old problem with new urgency. When a single journal is bundled into multiple aggregator packages, money leaks quietly. The IFLA project’s emphasis on cross-database duplicate detection is practical: the signal sits in the proxy logs, waiting for entity matching and normalization. Combine that with cost data and the case for canceling one package, or negotiating terms, becomes clear.
Forecasting usage matters in a different way. Acquisition timelines are slow, but demand can shift fast. A prediction model trained on semester cycles, program growth, and historic access gives selectors an early warning on high‑impact gaps. Tie that to course reserves or reading lists and the model can flag titles that will miss the window unless rushed.
The chatbot layer changes who can act. Subject librarians and managers don’t need a data analyst on call to ask, “Show me titles with rising access from nursing students but flat citation counts,” or, “Which platform delivers the fewest turnaways for our top 200 journals?” In other words, library generative AI shortens the path from question to decision, which often means the decision happens in time to matter.
What to watch: privacy, bias, and procurement cycles
Proxy logs can be sensitive. Even when names aren’t stored, combinations of timestamps, IP blocks, and resource paths can reidentify. Libraries should apply data minimization and access controls before building models or chatbot layers. The American Library Association’s privacy guidance is a good starting point for internal policy and vendor requirements (ALA).
Bias lurks in access data. Under-resourced departments generate fewer log lines, which can translate to fewer purchases if the model is left to run the show. Counter that by blending multiple measures of need. COUNTER‑conformant usage reports, interlibrary loan requests, turnaway counts, and course adoption data provide balance. The Project COUNTER Code of Practice helps align vendor metrics so comparisons are fair.
Procurement cycles introduce their own lag. Even with great forecasts, a model can only influence renewals if the team can act before lock‑in dates. That’s where the chatbot helps: it can surface time‑sensitive candidates for negotiation in minutes, not days, if fed with license metadata and renewal timelines.
A practical start for teams this fiscal year
Mahboobani’s poster is a proof point that the parts exist and can be stitched into a workflow. Here’s a simple plan to move from idea to impact:
- Define the boundary. Decide which databases and date ranges to include, then scrub EZproxy data for personal identifiers.
- Normalize entities. Map titles and ISSNs across platforms, and tag departments or programs with a consistent scheme.
- Add context. Join cost, license terms, COUNTER reports, turnaways, and course lists to the usage table.
- Set guardrails. Keep the generative assistant read‑only at first, log all prompts and responses, and require a human sign‑off for recommendations.
- Measure lift. Track cost‑per‑use before and after, time‑to‑decision for renewals, and user satisfaction among selectors.
Technical choices matter, but governance matters more. Name an owner for data quality. Write down how duplicate flags become action items. Decide when the model’s forecast outranks a faculty request and when it doesn’t. Those policies keep the system from drifting into “black box says no.”
Limits of EZproxy logs—and how to fill the gaps
EZproxy is great at showing authenticated activity, but it misses a lot. Off‑platform reading, open‑access copies, or PDF shares won’t always appear. Discovery behavior in learning platforms can be invisible too. That’s why the most defensible decisions will blend EZproxy analytics with COUNTER reports, discovery logs, link‑resolver data, and even citation patterns pulled from accepted bibliometrics sources.
Another gap is quality of the log itself. Institutional IP changes, VPN quirks, and misconfigured stanzas can fracture a single user’s session in awkward ways. Before modeling demand, fix the plumbing. OCLC’s EZproxy documentation is detailed for a reason; small configuration issues ripple into big data problems (OCLC).
What comes next for collection decisions with AI
The poster’s most interesting claim isn’t technical. It’s operational. Pair an explainable prediction model with a chatbot that speaks the language of selectors, and you get faster decisions that are easier to audit. Ask a question, see the evidence, and export the rationale into a renewal record. That’s the workflow libraries have wanted for years, now reachable with off‑the‑shelf parts.
Expect two near‑term shifts. First, duplicate detection will migrate from ad‑hoc checks to always‑on monitoring, shaving real money from renewals. Second, conversational analytics will spread to colleagues who avoided dashboards entirely. When answers come in plain English, more people ask better questions. That is the quiet power of library generative AI.
None of this removes judgment. It raises its impact. Libraries that treat the model and the assistant as tools—transparent, fallible, and documented—will convert data into choices that patrons feel at the login screen. As the IFLA project shows, the path from proxy logs to better access is short enough to walk now, and library generative AI makes the trip faster. For more on this, see nytimes.com.